Prompt Injection Is a Systems Problem, Not Just a Prompt Problem
Why instructions alone cannot secure tool-using AI systems—and how trust boundaries, permissions, isolation, and monitoring reduce the damage.
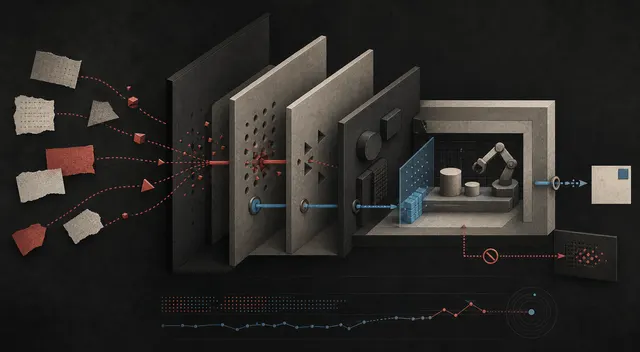
Prompt injection is often described as a wording contest: an attacker writes a malicious instruction, and a defender responds with a stronger system prompt. That framing is dangerously incomplete.
The real security problem appears when an AI system mixes trusted instructions with untrusted content and also has access to valuable data or consequential tools. No sentence at the top of a prompt can replace access control, isolation, confirmation rules, and monitoring.
Direct and indirect injection
A direct injection arrives from the person interacting with the model. The person may ask it to ignore a policy, reveal hidden context, or misuse an available tool.
An indirect injection is carried inside something the system reads: a webpage, email, document, issue description, database record, image, or tool result. The user may be acting in good faith while the retrieved content contains instructions intended for the model.
That difference matters. A conventional application normally treats document text as data. A language model can interpret the same text as an instruction, even when the developer intended it to be evidence or background material.
The NIST adversarial machine-learning taxonomy includes direct and indirect prompt injection among attacks affecting generative AI. This is not merely a chatbot etiquette problem; it belongs in the threat model of the complete application.
Why a stronger prompt is not a complete defence
System instructions are useful. They can define policy, identify untrusted material, and make undesirable behaviour less likely. But a model is a probabilistic interpreter, not a security boundary.
Instructions and data usually reach the same model context. Delimiters, warnings, and role labels communicate the developer’s intention, but they do not create the kind of isolation provided by a process boundary or an authorization check.
Attackers can also adapt. They can split instructions across fields, hide them in content, exploit transformations, or make an unsafe action appear necessary to complete the user’s legitimate goal. A defence measured against a fixed set of attack strings may fail against a determined attacker who can retry.
Anthropic’s published work on browser-use prompt-injection defences reports improvements from model training, classifiers, and red teaming while explicitly warning that no browser agent is immune. The practical conclusion is not that those controls are useless. It is that model-layer controls need independent layers around them.
Begin with assets and authority
Before choosing a detector, list what the AI system can reach and what it can change.
Sensitive assets may include:
- private messages and documents;
- customer or employee data;
- credentials and API tokens;
- source code and deployment systems;
- payment, purchasing, or account functions;
- the ability to send messages or publish content;
- internal instructions and security controls.
Then list the system’s authority. Can it only summarize text, or can it send email, modify a repository, approve a transaction, or execute code? Prompt injection becomes more consequential as authority and autonomy increase.
A read-only assistant with access to public documentation has a different risk profile from an agent that can browse private mail and send replies. They should not share the same controls merely because they use the same model.
Separate data from decisions
Treat retrieved content as evidence, never as authorization.
A document may contain a customer address, but it should not be able to authorize shipment. A webpage may describe a shell command, but it should not decide whether the agent executes that command. An email may request a password reset, but the request should still pass the application’s identity and approval process.
This separation is easier when the application uses typed operations. Instead of giving the model an unrestricted command shell, expose narrow functions with validated parameters. Instead of allowing arbitrary HTTP requests, provide a small allowlisted API. Instead of accepting a model’s claim that an action is approved, verify approval from trusted application state.
The model can propose an action. The application decides whether the action is allowed.
Minimize privileges and credentials
An agent should receive only the permissions required for the current task, for the shortest practical time.
Useful controls include:
- read-only credentials for research tasks;
- separate identities for separate tools and environments;
- short-lived tokens rather than permanent secrets;
- tenant-scoped access enforced outside the model;
- allowlists for destinations, repositories, and data sources;
- transaction limits and rate limits;
- explicit approval for irreversible or externally visible actions.
Do not put a powerful secret into the model context and then ask the model not to reveal it. If the model never receives a credential, an injected instruction cannot extract that credential from the model.
Isolate execution and network access
Code execution should occur in a constrained environment with a limited filesystem, process model, network policy, and lifetime. Sensitive host directories and credentials should be absent unless the task genuinely requires them.
Network egress deserves the same attention. If an agent can send arbitrary requests, an attacker has more opportunities to exfiltrate information. Restrict destinations and protocols, log connections, and separate fetching public content from calling privileged internal services.
Anthropic describes a similar layered principle in its engineering discussion of containing agents across products: constrain the environment, apply model-level safeguards, and limit the external content and tools the agent can reach. The important point is the overlap. Any one layer can fail without immediately exposing every asset.
Require confirmation at the right boundary
Human confirmation is useful only when the reviewer can understand what will happen.
“Allow the agent to continue?” is weak. “Send this exact message to these three external recipients?” is specific. A confirmation screen should show the action, target, important parameters, and material consequences. It should be generated from trusted application state, not solely from the model’s explanation.
Routine low-risk actions may be automated. High-impact actions—publishing, deleting, paying, changing access, or sending sensitive data—need stronger policy and often a second party.
Detect, test, and contain failures
Prompt-injection classifiers and input scanning can reduce risk, but they should feed a response policy rather than act as a magic gate. A suspicious input might disable tools, force read-only mode, require review, or prevent sensitive data from entering the session.
Testing should include indirect attacks inside every content type the system consumes. Test multi-step attacks, encoded text, conflicting documents, tool-output injection, and attacks that adapt after a refusal. Measure both attack success and the cost of false positives on legitimate work.
The OWASP LLM Security Verification Standard can help teams turn broad concerns into application requirements. The test plan still needs to reflect the actual tools, data, and trust boundaries of the product.
Log proposed and executed actions separately. Preserve the source content that influenced an action, the policy decision, the identity used, and the result. Monitoring should alert on unusual destinations, repeated denied actions, unexpected data volume, and permission changes.
Design for a successful attack
A mature threat model assumes that some attacks will bypass detection. Ask what happens next.
Can the compromised session read every customer’s data or only one record? Can it send information to any host or only approved services? Can it publish immediately or only create a draft? Can it alter logs? Are credentials automatically revoked when abnormal behaviour is detected?
These questions shift the goal from perfect prevention to bounded damage and reliable recovery.
The practical rule
Use prompts and model training to improve behaviour. Use security architecture to limit authority.
An AI system that processes untrusted content should be designed as though the model can occasionally follow the wrong instruction. Narrow tools, independent authorization, isolated execution, constrained network access, clear confirmations, and auditable actions make that mistake survivable.
Prompt injection cannot be solved by prose alone because the vulnerable object is not just the prompt. It is the system built around it.