Why Retrieval Quality Often Matters More Than a Larger Model in RAG
A practical method for diagnosing retrieval-augmented generation by measuring search, reranking, evidence coverage, and answer faithfulness separately.
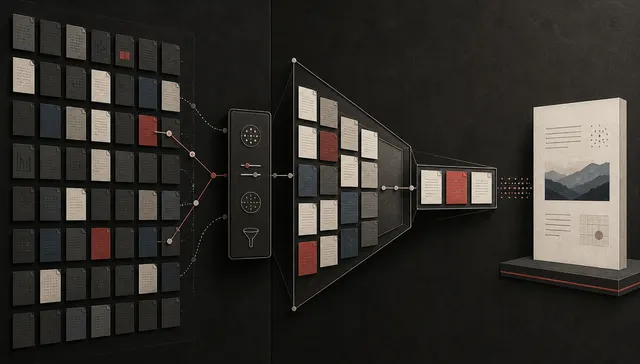
When a retrieval-augmented generation system gives a weak answer, replacing the language model is an appealing fix. Sometimes it works. Often it hides the real failure: the system never supplied the model with the evidence it needed.
A larger model may write a more convincing response from poor context. That is not the same as producing a better-supported answer.
The disciplined approach is to evaluate retrieval and generation separately before changing either component.
What RAG adds to a language model
The original retrieval-augmented generation paper described systems that combine a model’s learned parameters with an external, searchable memory. At query time, a retriever selects passages and the generator conditions its answer on them.
Modern production systems use many variations: keyword or vector search, hybrid retrieval, metadata filters, query rewriting, reranking, and several rounds of retrieval. The central dependency remains the same. The generator can only ground its answer in evidence that reaches its context.
This creates two broad failure classes:
- Retrieval failure: the right evidence is missing, incomplete, stale, or buried among irrelevant chunks.
- Generation failure: useful evidence is present, but the model ignores, distorts, or overextends it.
If those failures are measured only through the final answer, teams can spend weeks tuning the wrong layer.
Start with a query-and-evidence set
Build an evaluation set from the questions the system is expected to answer. For each query, identify the smallest source passages required for a correct response.
Include more than straightforward factual lookups:
- questions requiring one exact passage;
- questions requiring evidence from several documents;
- ambiguous questions that should trigger clarification;
- questions whose answer changed across document versions;
- questions the collection cannot answer;
- acronyms, product names, misspellings, and domain-specific phrasing;
- access-controlled questions where a user must not retrieve another tenant’s evidence.
Record document identifiers and versions, not only an ideal answer. Retrieval evaluation needs to know which evidence was available at the time of the test.
Measure whether the evidence was retrieved
For each query, inspect the ranked results before calling the language model.
Useful metrics include:
- Recall at k: how much of the required evidence appears in the first k results?
- Precision at k: how much of those results is actually relevant?
- Mean reciprocal rank: how early does the first relevant result appear?
- nDCG: how well does the ranking place more useful results near the top when relevance is graded?
The exact metric matters less than matching it to the task. A question requiring three policy clauses can fail even when the first result is relevant; recall across all required evidence is more informative. A support interface that displays only one result cares greatly about the first rank.
The BEIR benchmark demonstrates why one retrieval method should not be assumed to dominate every domain. Its heterogeneous datasets cover different retrieval tasks, and the published results show trade-offs between lexical, sparse, dense, late-interaction, and reranking approaches. The project’s reference implementation makes the datasets, metrics, and evaluation workflow inspectable. Internal evaluation should be similarly diverse, even when the production corpus is smaller.
Use a simple baseline
Do not begin with the most complicated embedding and agent pipeline available.
A lexical baseline such as BM25 is inexpensive, explainable, and often strong for exact names, identifiers, error messages, and specialized terms. Compare dense and hybrid retrieval against it. If a sophisticated system cannot beat the baseline on the actual query set, complexity is not justified.
Keep the same documents, relevance judgments, and ranking depth when comparing methods. Report performance by query type, not only as one average. Dense retrieval may improve paraphrased questions while damaging exact identifier searches; the average can hide both effects.
Chunking is part of retrieval
Search quality depends on the unit being indexed.
Chunks that are too large may mix unrelated subjects and consume context with irrelevant text. Chunks that are too small may separate a rule from its exception, a table from its heading, or a definition from the term it defines.
Test chunking strategies on evidence coverage. Preserve document structure where it carries meaning: headings, sections, list boundaries, table labels, code blocks, and page references. Store the parent document, version, date, access policy, and nearby context as metadata.
Overlap can help at boundaries, but heavy overlap creates near-duplicate results. Those duplicates can occupy the whole top-k window while still omitting another required section.
Filters can silently remove the answer
Metadata filters are powerful and dangerous. A wrong tenant, language, region, date, product version, or document-type filter can produce a clean-looking result set that never had a chance to include the answer.
Log filters with every retrieval request. Add tests for empty and contradictory filters. When access control affects retrieval, enforce it in the data layer rather than asking the model to ignore unauthorized results after they have been retrieved.
Freshness also needs explicit rules. Reindexing a changed document is not enough if obsolete chunks remain searchable. Tests should verify that superseded evidence is removed or clearly deprioritized.
Reranking cannot recover missing documents
A reranker can improve the order of an initial candidate set. It cannot select a document that the first-stage retriever never returned.
Measure both stages:
- candidate recall at a relatively large depth;
- ranking quality after reranking;
- evidence coverage in the final context sent to the model.
If candidate recall is poor, improve indexing, queries, hybrid search, or the first-stage retriever. If recall is strong but top results are noisy, reranking may help. If the final context loses necessary passages, inspect deduplication and context-packing rules.
Evaluate the answer against the retrieved context
Once retrieval is adequate, score generation separately.
Check whether the answer:
- addresses the question;
- is supported by the supplied passages;
- cites the correct source and location;
- distinguishes evidence from inference;
- refuses or asks for clarification when evidence is insufficient;
- avoids claims that come only from model memory.
The RAGAS paper separates dimensions such as retrieval relevance, use of context, and generation quality. A broader survey of RAG evaluation likewise treats retrieval and generation as distinct parts of the evaluation problem. Automated judges can accelerate regression testing, but calibrate them against human review and retain the underlying examples. A single “RAG score” can conceal the same component failures as a single answer-quality score.
Test counterfactual and unanswerable cases
A grounded system should change when its evidence changes.
Create a controlled test document with a fact that differs from common model knowledge. Verify that retrieval finds the document and the answer follows the supplied evidence. Then remove or update it and repeat the test.
Also include unanswerable questions. The correct result may be “the available documents do not establish this.” If the system always produces a fluent answer, retrieval improvements alone will not make it trustworthy.
Measure latency and cost by stage
Record time and cost for query rewriting, embedding, first-stage retrieval, reranking, context construction, model generation, and retries.
This makes trade-offs visible. A reranker that provides a small relevance improvement may still be valuable for high-cost errors, but not for every request. A larger generator may be unnecessary when better retrieval lets a smaller model answer from clear evidence.
Cache only with document versions and access scope in the key. Otherwise a fast cache can return stale or unauthorized evidence.
A diagnostic sequence
When answer quality falls, work through the system in order:
- Confirm that the authoritative document exists in the indexed corpus.
- Confirm that parsing preserved the relevant content and structure.
- Confirm that filters allow the document for this user and query.
- Measure whether the first-stage retriever returns every required passage.
- Check whether reranking keeps those passages near the top.
- Inspect the exact context assembled for the model.
- Only then evaluate whether the generator follows that context.
This sequence prevents model changes from masking data and retrieval defects.
The practical rule
A RAG system is not automatically grounded because it contains a vector database or displays citations. Grounding is an observed property: the right evidence is retrieved, preserved, used faithfully, and traceable in the final answer.
Improve the model when generation is the measured bottleneck. Improve retrieval when the evidence is missing or poorly ranked. Until those components are tested separately, choosing a larger model is mostly guesswork.