Securing the AI Supply Chain From Model to Production
A practical way to inventory, verify, constrain, monitor, and recover every dependency between an AI model and a production decision.
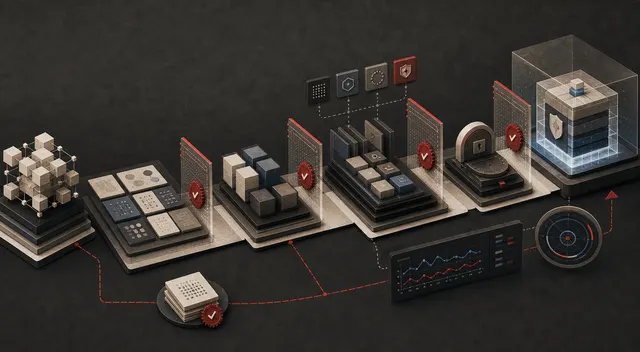
An AI application is not one model inside one service. It is a chain of models, datasets, packages, prompts, retrieval indexes, tools, credentials, build systems, deployment settings, and external providers. A team can verify the model file and still ship an unsafe system because something else in that chain changed.
Supply-chain security for AI begins with a simple operational question: can you identify every component that influenced a production output, verify where it came from, and contain it when it fails?
That is broader than scanning Python dependencies. It joins conventional software controls with model and data governance, runtime authorization, and incident response.
What belongs in the AI supply chain
A useful inventory follows the path from an input to a consequential output. Depending on the system, it may include:
- training, fine-tuning, evaluation, and retrieval datasets;
- base models, adapters, tokenizers, embedding models, and rerankers;
- model repositories, registries, conversion tools, and serialized artifacts;
- source code, containers, operating-system packages, and accelerator libraries;
- system prompts, policy files, tool descriptions, and evaluation suites;
- vector databases, search indexes, feature stores, and document parsers;
- hosted model APIs and other third-party services;
- plugins, agent tools, MCP servers, browser automation, and code sandboxes;
- identities, API keys, signing keys, and deployment credentials;
- build runners, registries, deployment platforms, logs, and monitoring rules.
This inventory should describe versions and relationships, not just names. “Uses an embedding model” is too vague. An incident responder needs to know which model revision built which index, which application revision queried it, and which customers or decisions were exposed.
NIST’s AI Risk Management Framework Core explicitly calls for policies that address risks from third-party software, data, and other supply-chain issues. It also calls for contingency processes when a third-party data source or AI system fails. Those outcomes connect procurement to engineering and incident response: approving a provider is not the end of the control.
Start with an evidence-producing inventory
An inventory becomes useful when it can answer questions during a release or incident. For each component, record:
- an immutable identifier such as a digest, commit, or exact provider version;
- its origin and responsible owner;
- license and usage restrictions;
- the environment and data classes it can reach;
- how its integrity was verified;
- evaluations or security checks required before promotion;
- deployments and downstream artifacts that depend on it;
- a removal, rollback, or provider-failover procedure.
Some providers expose only a moving model alias rather than an immutable revision. Record that limitation as a risk. If exact reproducibility is impossible, preserve request metadata, evaluation results, change notices, and the dates on which the hosted behavior was accepted.
An AI bill of materials can organize this information, but the document itself is not the control. A stale list generated for an audit will not reveal that yesterday’s index was built with a different embedding model or that a tool quietly gained write permission.
Verify artifacts and how they were produced
A checksum proves that two files are identical. It does not prove that either file is trustworthy. Teams also need evidence connecting an artifact to its source, build process, and authorized release.
The SLSA specification provides a useful model for incrementally improving software supply-chain guarantees. Its build and source tracks cover provenance, source control, build platforms, and verification. AI teams can apply the same principle to code, containers, model packaging, conversion steps, and evaluation artifacts.
Practical controls include:
- pinning dependencies and model revisions rather than following mutable tags;
- verifying signatures or trusted digests before promotion;
- building in isolated, ephemeral environments;
- separating build identities from deployment identities;
- recording provenance outside the artifact it describes;
- requiring review for changes to training data, prompts, policies, and tools;
- preventing a build job from rewriting its own audit evidence;
- reproducing selected builds and comparing their outputs where feasible.
Serialized models deserve special care. Some formats can execute code when loaded. Prefer formats designed for data-only loading, scan artifacts before use, and load untrusted artifacts in an isolated environment without credentials or unnecessary network access.
Treat data as executable influence
Training and retrieval data do not execute like a binary, but they influence model behavior and production decisions. That makes unauthorized data changes a security issue, not merely a quality problem.
For each dataset or corpus, preserve its origin, collection window, transformation steps, access rules, and quality checks. Separate raw, reviewed, and production-approved data. A principal that can submit data should not automatically be able to approve the resulting model or index.
Retrieval systems add another changing artifact: the index. Record the source-document revision, parser, chunking configuration, embedding model, filters, and build time. Without this lineage, a team may be unable to remove a poisoned document or determine which answers it influenced.
The NIST Generative AI Profile frames risk management across the AI lifecycle and includes governance, content provenance, testing, and incident disclosure concerns. The important operational lesson is that data controls, evaluations, and post-deployment monitoring need to remain connected; a pre-release dataset review cannot guarantee future behavior.
Evaluate the assembled system, not the model alone
A model can pass a benchmark while the application fails because retrieval returns the wrong document, a parser drops important context, a tool accepts unsafe parameters, or a policy is not enforced outside the prompt.
Every releasable configuration should therefore include the model, prompt and policy versions, retrieval configuration, available tools, permissions, and relevant infrastructure. Test that complete configuration against:
- expected task quality and known edge cases;
- malicious and malformed inputs;
- data leakage and cross-tenant access;
- tool misuse and unauthorized side effects;
- provider errors, timeouts, and degraded responses;
- rollback and failover behavior;
- logging completeness and alert quality.
Promote the configuration as one release unit. If any security-relevant component changes, run the proportionate evaluation again. A “minor” prompt edit or tool-schema change can be more consequential than replacing a library.
Put trust boundaries around tools and providers
Third-party models and tools should not inherit broad authority merely because they are convenient to integrate. Define what data each provider may receive, where it is processed, how long it is retained, and what happens when the service changes or becomes unavailable.
For agent tools, enforce authorization in application code. The model can propose a function call, but a trusted policy layer should validate the identity, target, parameters, data classification, rate, and approval state. Use separate, short-lived credentials for separate tools and environments. Do not expose a production credential to a research or summarization task.
The UK NCSC’s Guidelines for secure AI system development divide the lifecycle into secure design, development, deployment, and operation. They specifically include supply-chain security, asset management, infrastructure protection, logging, monitoring, and update management. CISA and partner agencies describe the same guidance as an application of secure-by-design principles.
That lifecycle view prevents a common gap: engineering verifies an artifact before release, but operations later accepts silent provider changes or expands tool permissions without repeating the threat assessment.
Monitor drift in code, behavior, and authority
Traditional integrity monitoring looks for changed files and packages. AI systems also require behavioral and authority monitoring.
Track changes to model aliases, provider terms, moderation behavior, prompts, retrieval sources, tool definitions, permissions, and network destinations. Compare production behavior with a small, stable evaluation set and investigate meaningful shifts. Log which component versions and data sources contributed to high-impact actions.
Useful alerts include:
- an unapproved model or package digest entering an environment;
- a retrieval source appearing outside the approved corpus;
- a tool gaining a new operation or wider scope;
- unusual output volume or new external destinations;
- a sudden change in refusals, unsafe actions, or sensitive-data exposure;
- provenance or evaluation evidence missing from a release.
Monitoring must lead to an action. Predefine when to disable a tool, isolate a tenant, roll back a release, revoke credentials, switch providers, or stop processing a data source.
Prepare for replacement and revocation
Supply-chain plans often explain how to add a dependency and say little about removing one. Removal is harder when a model generated derived datasets, an embedding model shaped a large index, or an external service retained data.
For critical components, rehearse:
- identifying every affected deployment and downstream artifact;
- stopping new use without destroying evidence;
- revoking relevant credentials and trust relationships;
- rebuilding derived artifacts from a known-good point;
- validating the replacement configuration;
- notifying affected operators or users when required;
- documenting what the inventory or controls failed to reveal.
A provider failover is not safe merely because both APIs accept similar requests. The replacement may use different retention rules, safety behavior, context limits, or tool-call semantics. Treat failover as a pre-evaluated configuration, not an emergency string substitution.
A practical minimum baseline
A small team does not need a complex platform before it can improve. A defensible baseline is:
- one versioned inventory covering models, data, code, services, tools, and identities;
- immutable pins or recorded limitations for every production dependency;
- automated integrity and provenance checks in the build path;
- isolated builds and least-privilege deployment credentials;
- system-level evaluations tied to each releasable configuration;
- application-enforced authorization for every consequential tool;
- logs that connect actions to component versions and approvals;
- tested rollback, revocation, and third-party failure procedures.
The goal is not to prove that every component is harmless. It is to make trust explicit, changes visible, authority narrow, and recovery possible. When a model, dataset, package, tool, or provider fails, the team should be able to determine what changed, what it affected, and how to contain it without guessing.